Sifting through 12,000 high school tournament action shots to build 40 individual athlete galleries does not require spending entire weekends manually inspecting jersey numbers.
By pairing local optical character recognition with roster-mapped metadata injection in Adobe Lightroom Classic, you can route thousands of player photos into isolated parent delivery albums in under 45 minutes per game.
Unlike facial recognition software that triggers complex biometric privacy laws, automated jersey OCR relies strictly on visible uniform numbers to protect student privacy while eliminating manual tagging.
The High School Tournament Bottleneck: Manual Sorting vs. OCR
Parent booster organizations expect prompt delivery of high-resolution game action photos after every weekend tournament. When you cover 40 student-athletes across four matches, you easily capture 12,000 raw frames.
Capturing clear jersey numbers starts courtside, where dialing proper settings for high school gym sports under harsh gym lighting prevents motion blur from degrading digit readability.
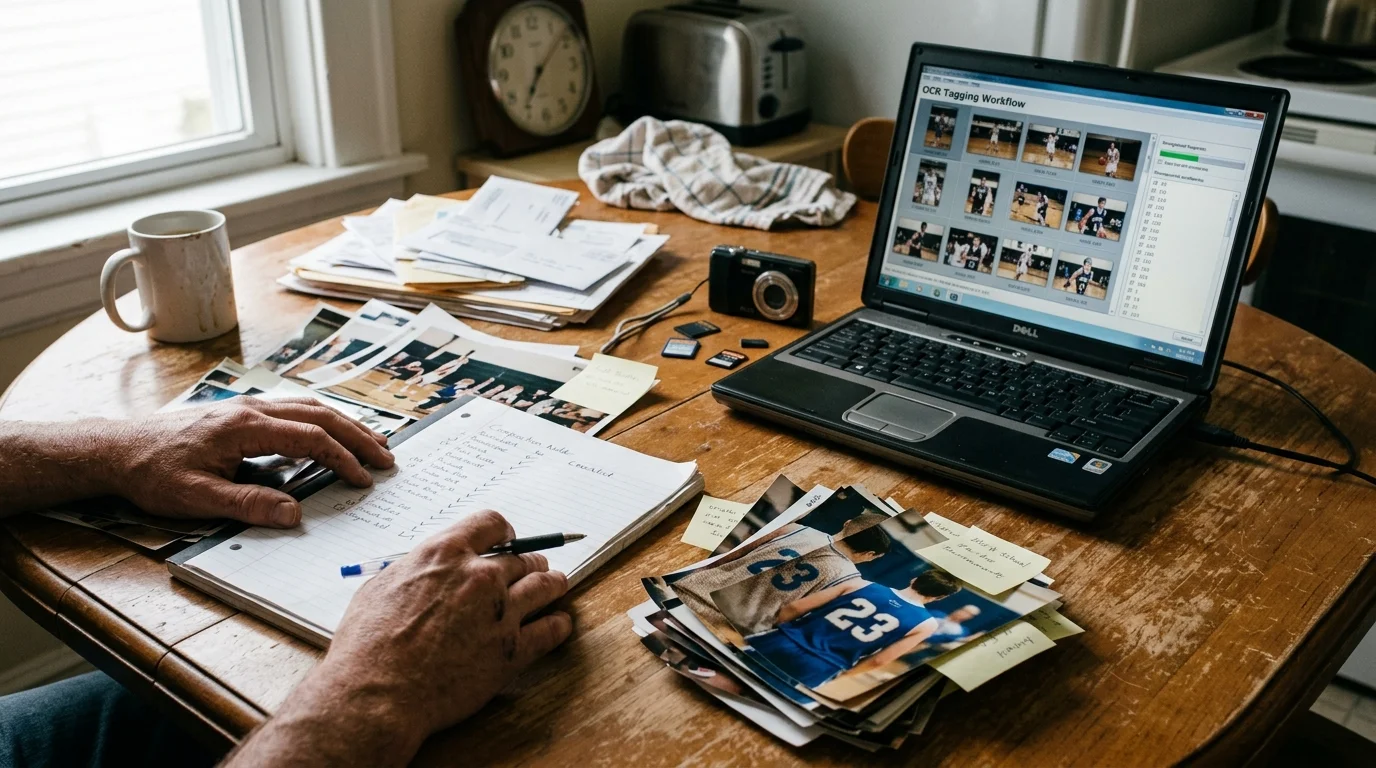
Manually inspecting jersey numbers requires approximately three to five seconds per image. At that speed, cataloging a full tournament takes between 10 and 16 hours of monotonous sorting before editing even begins.
This bottleneck delays gallery delivery and exhausts volunteer booster parents. Frustrated parents often receive photos days after the emotional momentum of the tournament victory has faded.
Automated optical character recognition reads uniform digits directly from camera bursts, transforming raw game action into structured metadata in seconds.
Optical character recognition engines scan uniform textiles to isolate high-contrast numbers on jerseys and shorts. When you understand digital photography workflows and sharp edge contrast, you can optimize camera focus parameters so OCR software detects digits instantly.
The software matches detected numbers against a preloaded team roster file. It writes player names, positions, and jersey digits directly into your catalog metadata.
Adopting an automated jersey OCR pipeline reduces your per-game sorting time from four hours down to 45 minutes. You can distribute personalized season galleries to 40 families before the weekend ends.
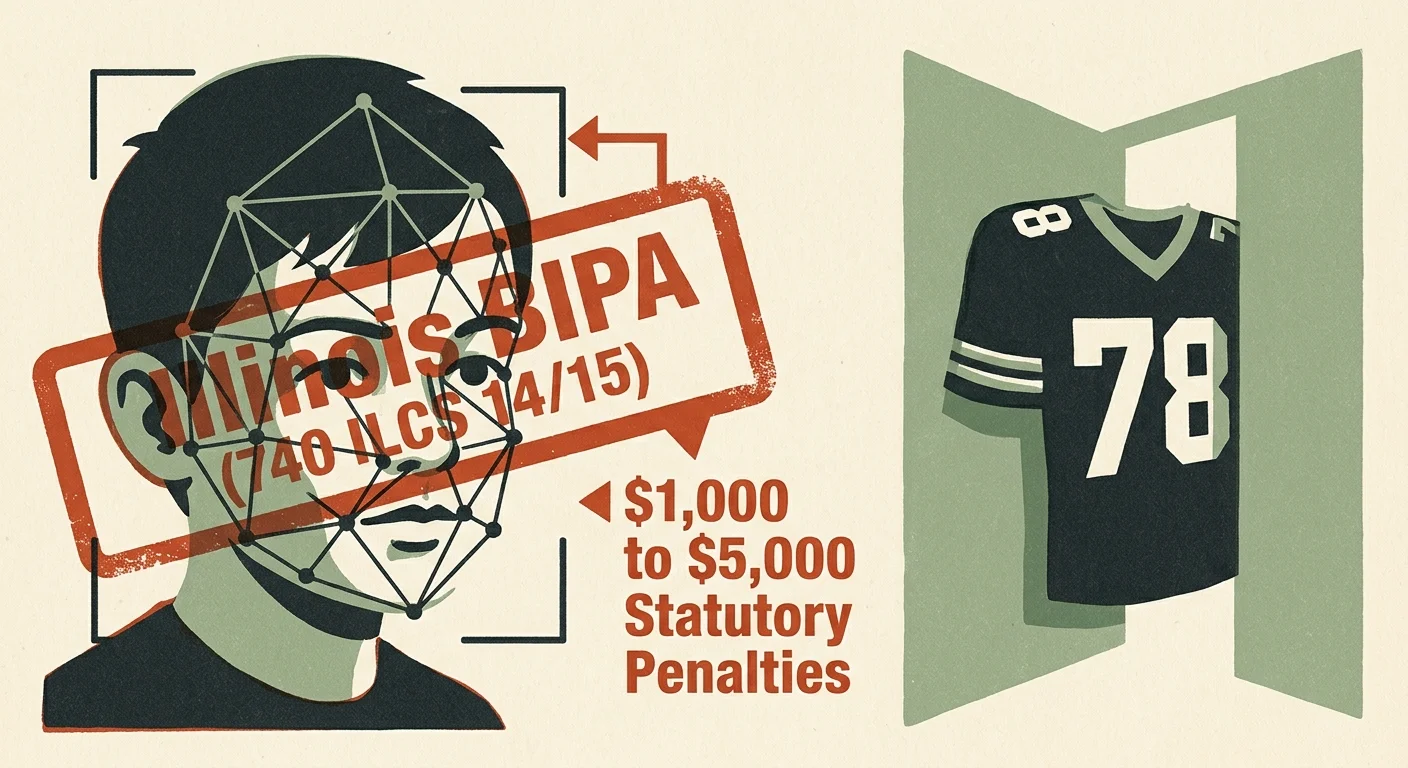
Biometric Privacy and Legal Guardrails: Why Jersey OCR Beats Facial Recognition
Many digital asset platforms advertise automated facial recognition as the easiest way to organize player galleries. For youth and high school sports photographers, facial recognition introduces severe legal vulnerabilities.
This privacy-first strategy parallels methods used in local machine learning workflows, where local computer vision runs entirely on-device without exposing subjects to cloud surveillance risks.
The Illinois Biometric Information Privacy Act (740 ILCS 14/15) imposes statutory damages of $1,000 for negligent violations. Reckless or intentional violations carry statutory penalties of $5,000 per individual scan.
Capturing facial geometry scans of high school minors without explicit, written parental consent creates unacceptable financial exposure for booster clubs and independent sports photographers. Federal mandates like the Children’s Online Privacy Protection Act enforce similar data constraints.
Jersey OCR provides a completely non-biometric indexing alternative. The computer vision model detects graphic print characters on uniforms rather than anatomical facial markers.
Text on athletic jerseys constitutes public information openly displayed on the field. Indexing photographs by uniform numbers respects athlete privacy and fully bypasses biometric regulatory definitions.
Desktop-based OCR tools process every frame locally on your workstation. Your files stay off third-party public cloud servers, safeguarding student images from commercial data mining.
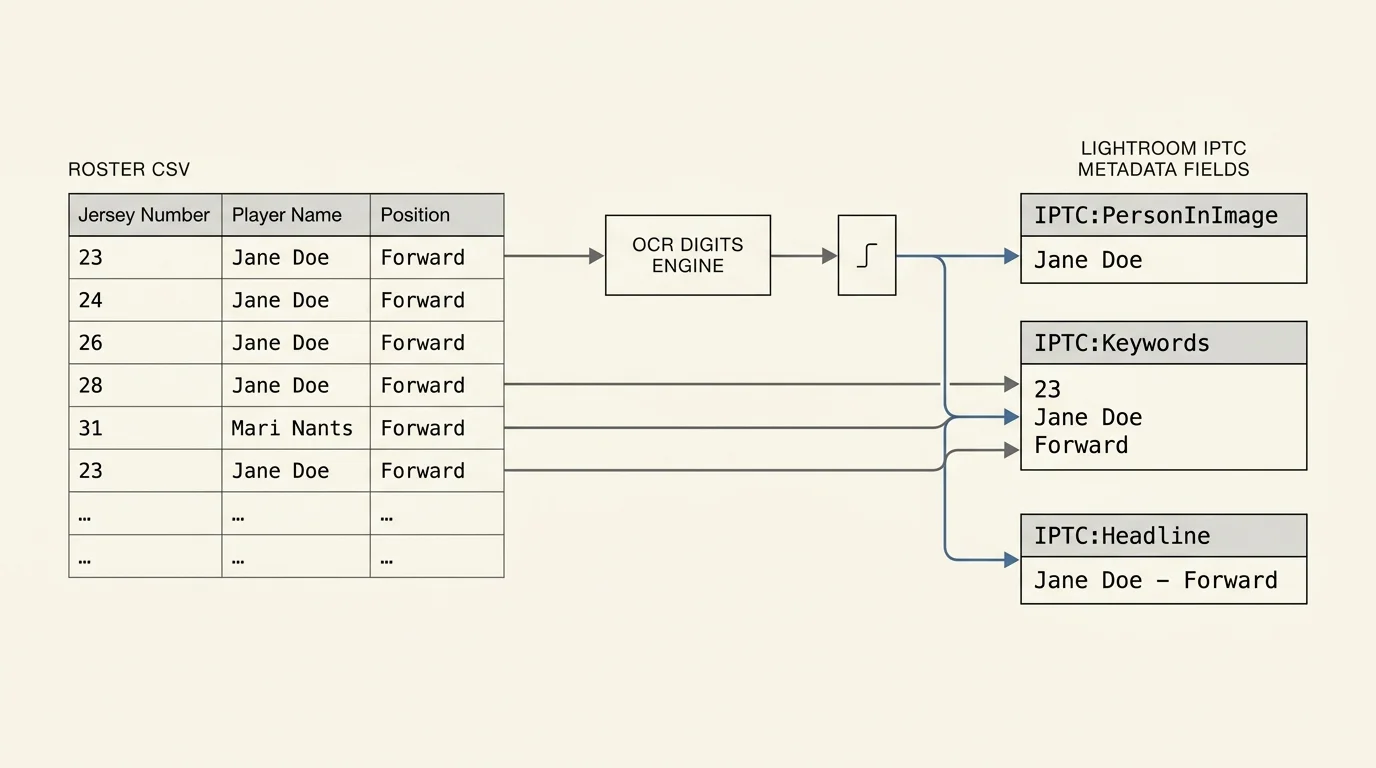
Essential Metadata Standards: Mapping IPTC Fields for Roster Ingestion
Efficient photo retrieval relies on universal metadata architecture rather than proprietary software folders. To organize athlete galleries in Lightroom Classic reliably, write OCR data directly to International Press Telecommunications Council (IPTC) fields.
Adhering to IPTC Photo Metadata standards ensures that every image file retains its athlete tags permanently. According to the Library of Congress digital preservation guidelines, embedding standardized metadata into file headers safeguards digital collections against proprietary software obsolescence.
When the OCR engine parses a uniform number, it cross-references your roster spreadsheet to write standardized tags into three core IPTC attributes:
- Keywords: Injects raw jersey numbers and athlete tags, such as “Jersey_14” and “Varsity_Soccer”.
- PersonInImage: Populates the student’s legal name, ensuring Lightroom Classic’s search engine indexes the athlete directly.
- Caption-Abstract: Writes descriptive match context, such as “Forward Marcus Vance (14) attacks the goal during tournament semifinals.”
Embedding this metadata directly into original raw sidecar files or exported JPEG images avoids duplicating files on your storage drives. A single image file appears across multiple filtered collections without consuming extra hard drive space.
Standardized IPTC tags remain fully readable across Adobe Lightroom, Photo Mechanic, and web hosting platforms. You can migrate your photo library to different platforms in the future without losing athlete sorting data.
Jersey Recognition Software Comparison: Local Tools vs. Cloud Platforms
Selecting the right recognition utility depends on whether you prefer desktop processing or hosted gallery delivery. High school team photo workflow requirements favor local tools that handle heavy raw file volumes without continuous subscription overhead.
The following table compares leading jersey identification engines and team photo management platforms:
| Platform | Operating Environment | Pricing Structure | Roster Matching Mode | Biometric Risk Level |
|---|---|---|---|---|
| Fieldframe | Lightroom Classic Plugin | Annual license / flat tier | Local CSV spreadsheet lookup | Zero (pure OCR) |
| GalleryID (MatchID) | Local Desktop App | $20/month or $200/year | Local CSV roster synchronization | Zero (pure OCR) |
| RaceTagger | Desktop / Hybrid | Free tier; volume packs from €39 | Local CSV starting list matching | Zero (bib/jersey OCR) |
| GotPhoto | Cloud Gallery Platform | Free tier (12% fee) or $9.90–$49.90/mo | Cloud roster and QR card indexing | Low (card/metadata based) |
| PhotoDay | Cloud Gallery Platform | 10% transaction fee model | Cloud roster with optional face-find | Moderate to High (if face-find active) |
| PhotoShelter AI | Cloud Enterprise DAM | Enterprise tier quote | Real-time cloud roster integration | Moderate (uses dual OCR/face scans) |
For independent high school sports photographers, desktop tools like Fieldframe and GalleryID offer the fastest turnaround. They scan RAW and JPEG previews directly on your local solid-state drives without requiring lengthy cloud uploads.
Cloud platforms like GotPhoto and PhotoDay excel when selling individual prints directly to parents. However, local plugins remain superior for sorting and editing multi-game tournament files before publishing.
Step-by-Step Fieldframe and Lightroom Classic OCR Implementation
Implementing an automated pipeline using Lightroom Classic and an OCR plugin requires careful preparation. Follow these sequential steps to sort sports photos by jersey number efficiently.
Incorporating systematic steps like these helps prevent catalog buildup, much like following a daily photo organization routine after major shooting sessions.
Step 1: Structure Your Team Roster CSV
Before the tournament begins, request the official team roster from the athletic director. Create a clean comma-separated values (CSV) spreadsheet using standard UTF-8 formatting.
Format the columns using these exact headers: JerseyNumber, FirstName, LastName, Team, and GradYear. Ensure single-digit numbers do not contain unnecessary spaces.
Step 2: Ingest and Rapid Cull in Lightroom Classic
Import your game memory cards into Lightroom Classic using the “Build Standard Previews” setting. Do not waste computer processing cycles on 1:1 previews during the initial import phase.
Run a rapid first pass to reject out-of-focus frames, blinking team bench shots, and misfires. Eliminating discarded images first reduces the total frame volume your OCR plugin must analyze.
Step 3: Execute the OCR Plugin Analysis
Select all remaining keepers in the Lightroom Library Grid view. Open your OCR plugin, such as Fieldframe or GalleryID, and link your prepared roster CSV file.
Initiate the scan. The algorithm evaluates bright character contours on athlete chests, backs, and shorts, automatically writing matched student names into the IPTC PersonInImage field.
Step 4: Build Dynamic Smart Collections for Each Athlete
Instead of manually dragging photos into individual folders, establish dynamic Smart Collections for your 40 athletes. Create a collection set named “Varsity Tournament Players.”
Inside the set, add a Smart Collection for each player. Set the rule criteria to: Person in Image contains [Player Name] or Keywords contain [Jersey_Number].
Lightroom automatically populates each player’s folder as soon as metadata is written. When you add new images from subsequent tournament rounds, the Smart Collections update instantly without manual intervention.
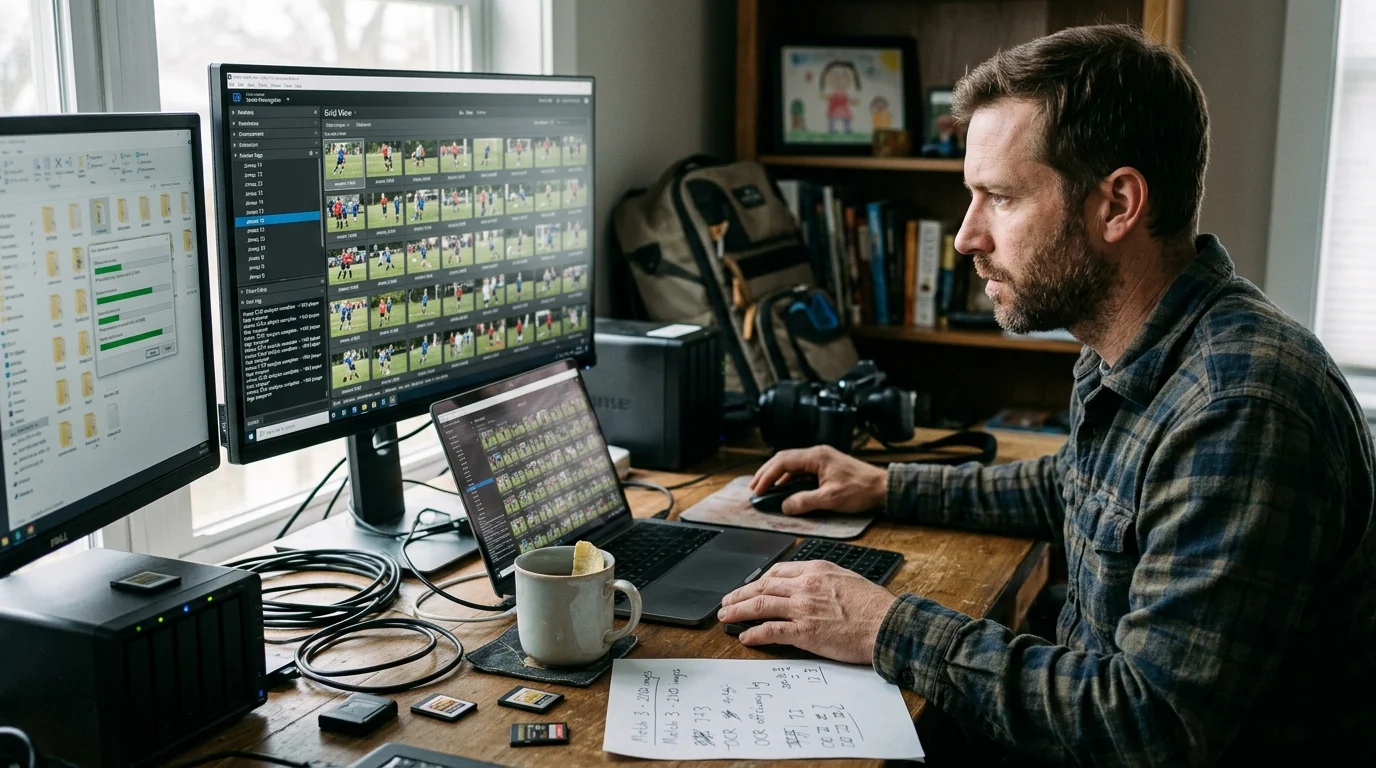
Worked Example: Processing a 12,000-Photo Tournament in 45 Minutes per Match
To understand the operational savings, examine this realistic scenario covering a weekend high school regional basketball tournament. You photograph four games, capturing roughly 3,000 frames per game for a cumulative total of 12,000 exposures.
After OCR routing assigns player tags, pairing this pipeline with batch editing for large photo collections ensures rapid proof delivery while action excitement remains high.
Your goal is to distribute 40 unique athlete galleries to waiting booster club parents. Here is how your time allocates for each 3,000-photo match:
Minutes 00:00 to 15:00: Fast Ingest and First-Pass Cull
You ingest 3,000 raw frames from two CFexpress cards using high-speed readers onto an NVMe solid-state scratch drive. Running through the images in Lightroom’s Library module, you reject 1,200 unusable frames.
This leaves exactly 1,800 sharp action frames ready for processing. Total time consumed: 15 minutes.
Minutes 15:00 to 27:00: Automated Batch OCR Tagging
You select all 1,800 culled frames and trigger the OCR plugin linked to your 40-player roster CSV. Processing at approximately 2.5 frames per second on a modern multi-core processor, the software scans all images in 12 minutes.
The plugin successfully identifies and writes IPTC metadata for 1,530 photos automatically. That represents an immediate 85 percent automated success rate on dynamic action shots.
Minutes 27:00 to 37:00: Quick Exception Review
You isolate the 270 unassigned photos using a Smart Collection set to Keywords does not contain Jersey_. These frames represent players facing away, extreme scrums, or partially occluded uniforms.
You review these frames in Grid view. You manually apply jersey keywords to 200 of them in 10 minutes by selecting clusters and typing the number into the Keywording panel. The remaining 70 general crowd or coach shots remain unassigned.
Minutes 37:00 to 45:00: Automated Gallery Export
With all 1,730 player action photos tagged, your 40 athlete Smart Collections are fully populated. You select all 40 collections and trigger a batch export preset.
The export script routes watermarked web proofs into 40 distinct subfolders named by player. You upload these folders directly to your gallery distribution host in the final eight minutes.
By investing 45 minutes per game, you process the entire 12,000-shot tournament in three total hours of work. Manual tagging of that same tournament would have consumed 14 hours of tedious labor.
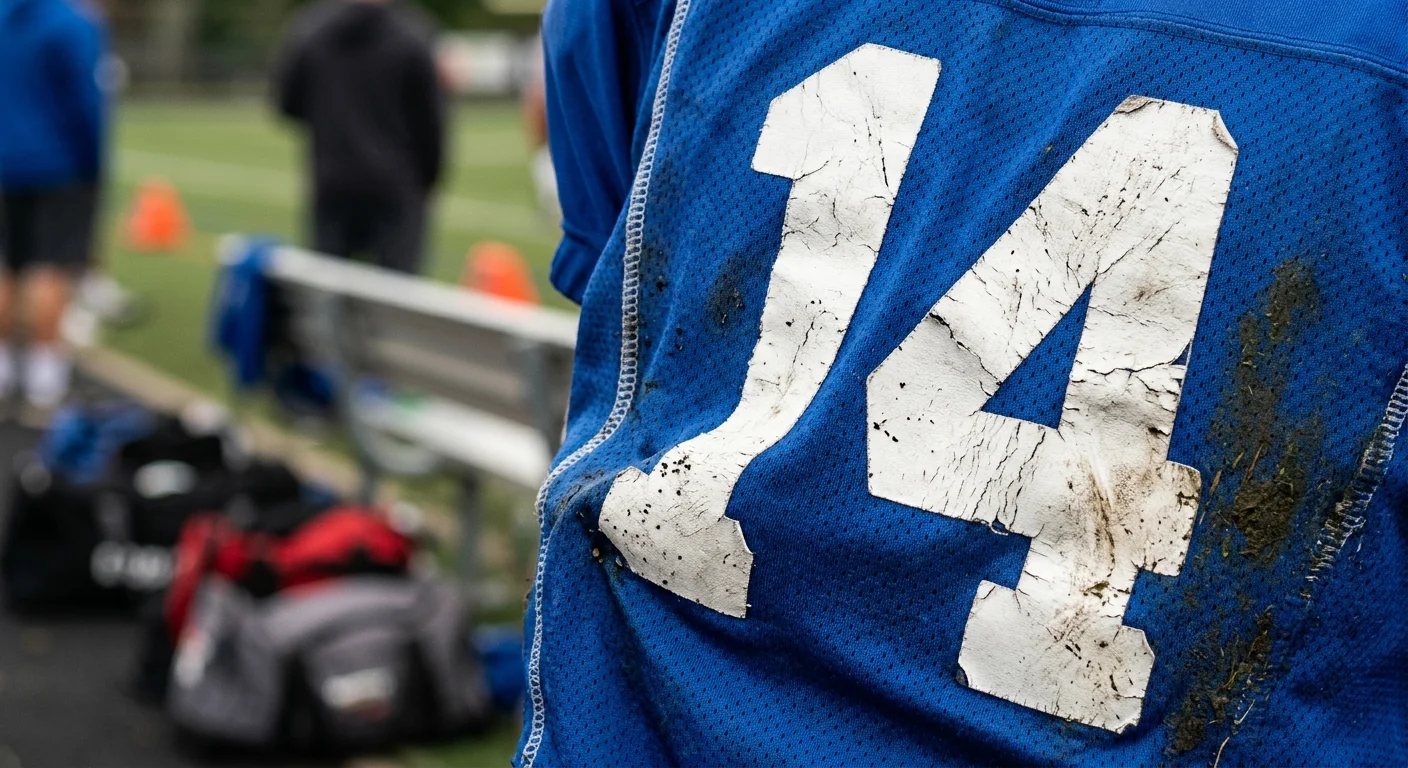
Handling Occluded Numbers, Dirt, and Edge Cases
Action sports present difficult conditions for character recognition algorithms. Fast-paced collisions, dynamic dives, and angled running strides frequently turn jersey numbers away from the camera lens.
Mud, wrinkled mesh fabric, and heavy shadows can also reduce OCR recognition accuracy. Employing specific capture and sorting strategies prevents these physical obstacles from derailing your workflow.
Take advantage of sequence burst propagation inside Lightroom. High-speed drive modes capture bursts of five to ten frames during a single offensive drive.
Even if an athlete turns away mid-play, the first or last frame of the sequence usually displays a readable jersey number. Tagging the legible frame allows you to sync the metadata across all adjacent frames in that burst with a single keystroke.
Watch for visual secondary anchors during exception reviews. Athletes display identifiable accessories like distinctive cleat colors, knee braces, colored wristbands, or specific hairstyles.
Identify these accessories once at the start of your manual review pass. You can tag occluded angle shots in seconds without pausing to verify uniform numbers.
For contact sports like football or ice hockey, configure your OCR engine to scan both helmet decals and uniform shoulders. Expanding detection regions significantly increases your initial automated match rate.
Frequently Asked Questions
Does jersey OCR software work reliably on single-digit uniform numbers?
Yes. High-quality OCR models easily detect single digits such as 3, 5, or 8, provided the uniform fabric offers adequate contrast against the printed numeral. Ingesting an accurate roster CSV prevents false matches by restricting database lookups strictly to active roster digits.
Can character recognition read dark jerseys with low-contrast print?
Subdued or low-contrast uniforms reduce optical recognition accuracy. You can overcome this during Lightroom ingest by applying a temporary high-contrast development preset that lifts shadows and boosts contrast before running your OCR plugin scan.
Why is jersey OCR safer than facial recognition for high school sports?
Jersey recognition detects printed graphic shapes on athletic uniforms, completely bypassing biometric facial geometry scans. This eliminates statutory liability under strict state privacy statutes like Illinois BIPA and complies with federal youth data privacy laws.
Do I have to duplicate photo files to create individual player galleries?
No. Using IPTC metadata tags and Lightroom Smart Collections allows single master files to appear in separate athlete folders dynamically. This metadata-driven sorting technique saves hundreds of gigabytes of drive storage during long tournament weekends.
Disclaimer: This article is for informational purposes only. When handling valuable or irreplaceable photographs, consider consulting a professional conservator. Always test preservation methods on non-valuable items first.